WheatOmics 2.0 · Resources
Download data
Genome assemblies, transcript sets, co-expression tables, 660K genotype data and JBrowse track documentation — everything behind the WheatOmics analyses.
1. Genome sequences
All genomes were downloaded from published papers; you can get them from the NCBI Assembly database. The published papers are also listed in the BLAST, GetSequence, PrimerServer 2 and JBrowse pages.
2. Transcripts generated from published data
We downloaded the published transcriptome data from the NCBI SRA database, mapped reads to the Chinese Spring genome, and merged the assemblies with the TACO pipeline. The resulting transcript sequences are available as TACOv1.tar.gz with password 1q6k.
4. Co-expression tables
The co-expression tables (wheat grain and multiple tissues) can be downloaded here with password wuw3.
3. Omics data in JBrowse
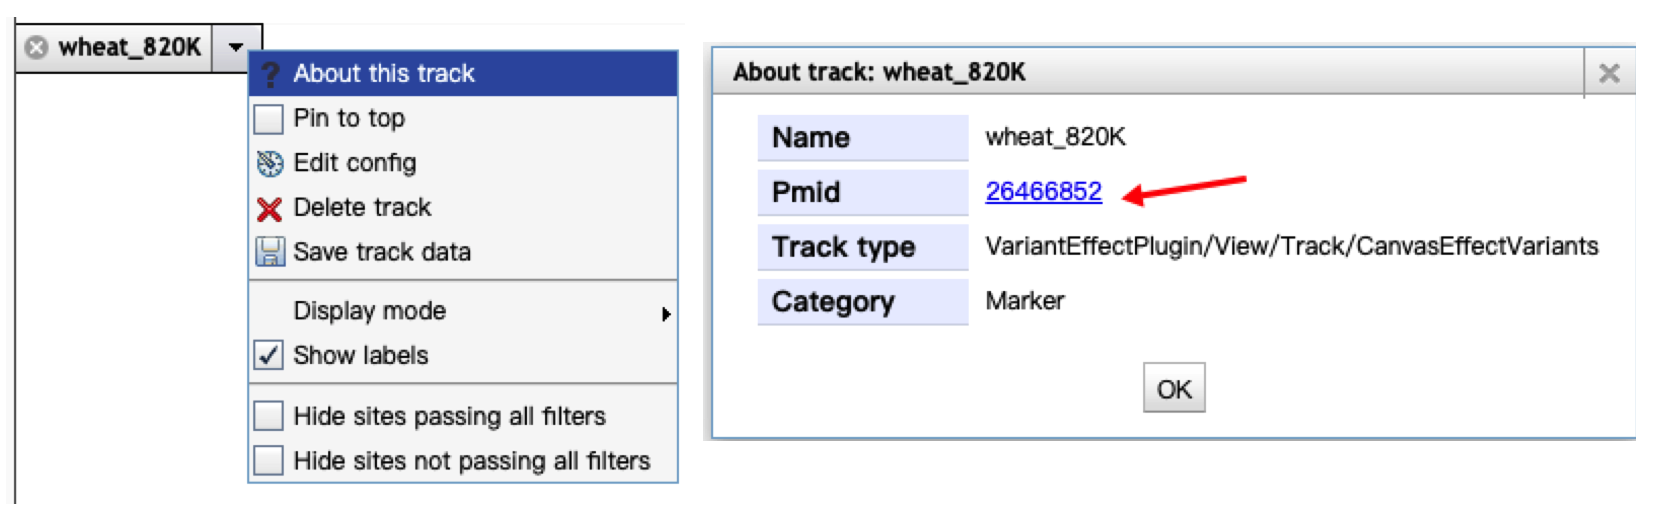
Open the JBrowse gateway and read the "About this track" panel for details of each track. Contact us at shengweima@icloud.com if you have a question about the JBrowse data.
The order information for the EMS mutants (Jimai 22 and Cadenza/Kronos) is available by right-clicking the mutation.

5. Wheat 660K genotype for 343 common wheat accessions
The genotype data can be downloaded here with password vn7m.